01
ETL
Extract, Transform and Load
Pipelines that extract data from several sources, process it according to business rules and load it into the destination with integration and quality.
PentahoSpark
Data Engineering
ETL, Data Lake and Data Warehouse for a single, reliable base ready for BI and AI.
What we deliver
ERPs, CRM, APIs, spreadsheets and databases brought together in one place.
Full history stored in a scalable, cost-effective way.
Facts and dimensions modeled for fast BI queries.
Quality rules, versioning and data access control.
Specialties
Extract, Transform and Load
Pipelines that extract data from several sources, process it according to business rules and load it into the destination with integration and quality.
Storage at scale
Large volumes of raw data stored in a scalable, cost-effective way, ready for advanced analytics and machine learning.
Data organized for decision-making
Data from different sources centralized in an organized repository, with fast queries for strategic decisions.
Architecture
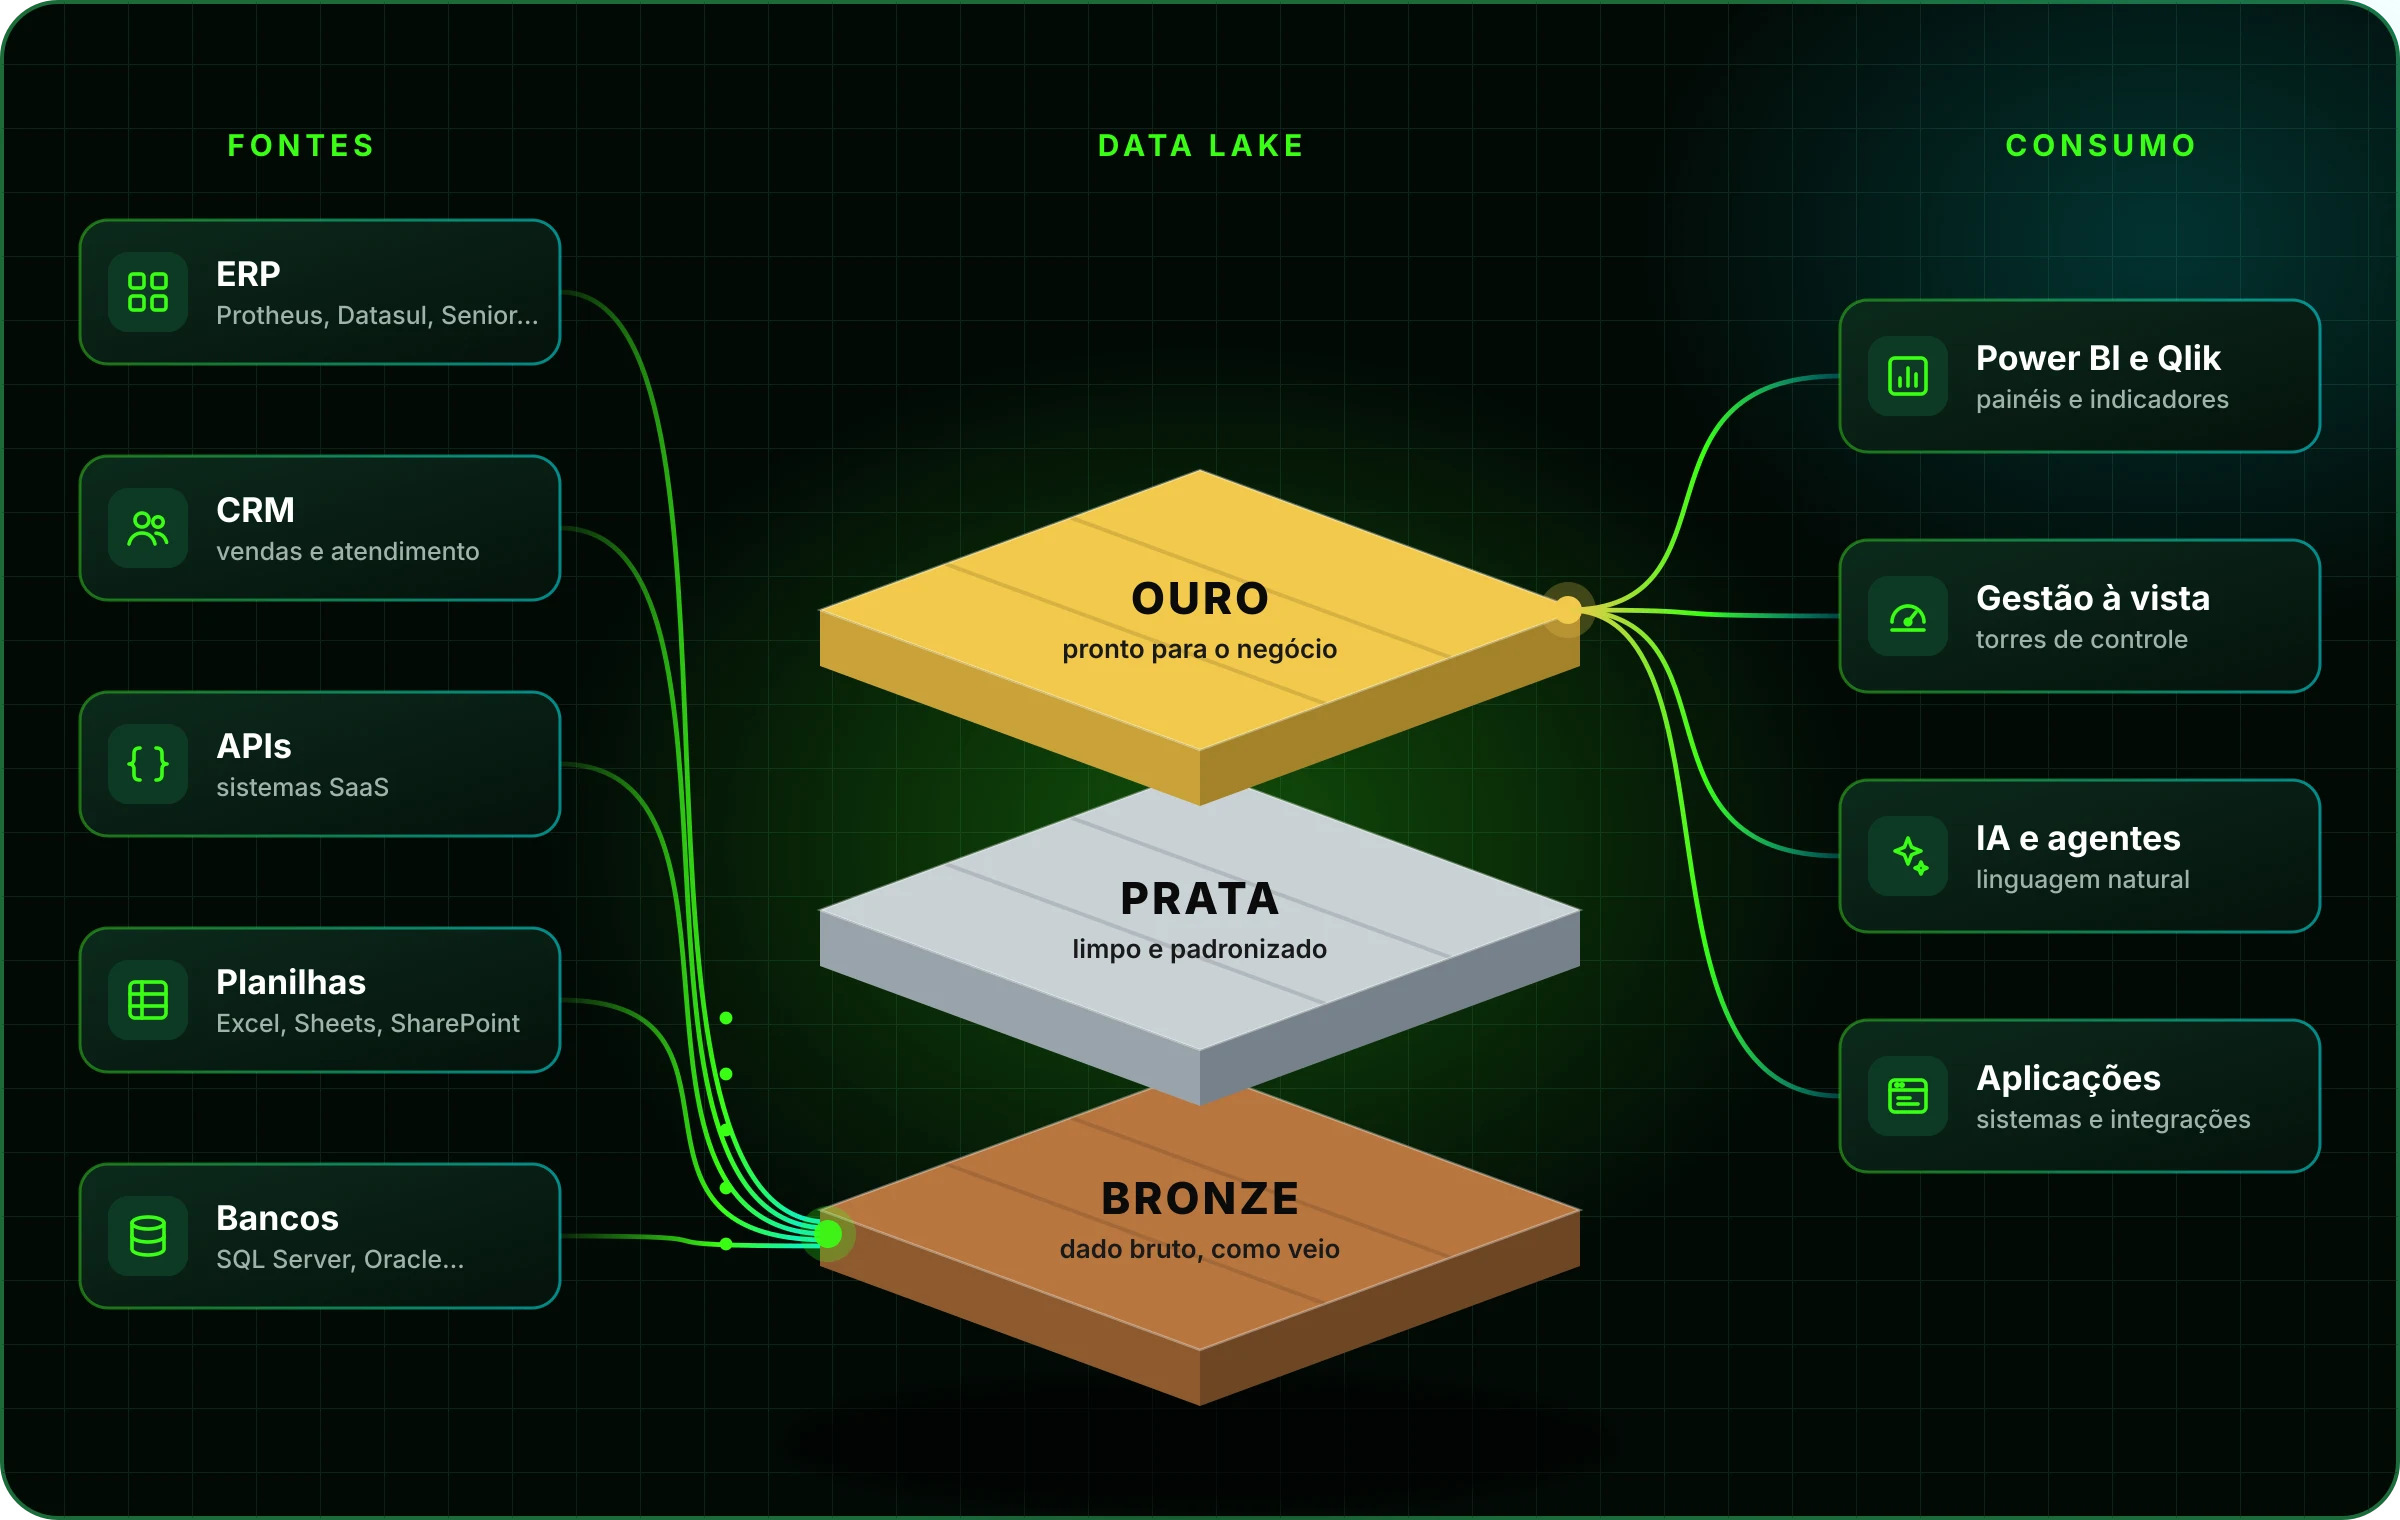
The medallion architecture separates what arrived from what was processed and from what the business consumes. Each layer has a clear role.
Ingestion
Data extracted from sources as-is, with incremental loads: only what changed since the last run comes in.
Processing
Clean, standardized, deduplicated data, updated by MERGE and validated by quality rules.
Business model
Dimensional model with facts and dimensions per area, ready for dashboards, reports and AI agents.
Platforms
We choose the platform based on your cost, volume and team scenario, not the other way around.
 Cloud
Lakehouse, pipelines, notebooks and dataflows integrated with Power BI on a single platform.
 Cloud
Spark pipelines and notebooks, with an integration runtime that reaches databases inside your network.
 Cloud
Lakehouse on Delta Lake with table optimization, cleanup routines and data quality at scale.
 Cloud
Data warehouse with a landing zone and procedures that take raw data to the final model.
 On-premises
A lake on your own server with Spark, Delta Lake, MinIO and Airflow: full control, no cloud capacity costs.
 Hybrid
Visual ETL for dozens of sources, with versioning and automated deployment.
Sources
Why it works
Instead of reloading everything every day, we move only what changed. Loads get faster and cheaper, and every version of the data is recorded.
# CDC: só o que mudou desde a última cargadf = (spark.read.jdbc(url, "erp.pedidos").where(col("updated_at") > checkpoint))df.write.format("delta").mode("append") \.save("s3a://lake/bronze/pedidos")
-- bronze → prata, só o que mudouMERGE INTO prata.pedidos pUSING bronze.pedidos_cdc cON p.id = c.idWHEN MATCHED THEN UPDATE SET *WHEN NOT MATCHED THEN INSERT *
# orquestração: roda de hora em hora@dag(schedule="@hourly")def vendas():extrair = spark_job("extrair_cdc")tratar = spark_job("bronze_para_prata")modelar = spark_job("prata_para_ouro")extrair >> tratar >> modelar
Cases
Why it matters
An AI agent only answers well if the data is organized. With a modeled gold layer, the AI navigates a ready, auditable business model instead of guessing.
What you get
How we deliver
We map systems, volumes and business rules, and define the platform that makes sense.
Ingestion, processing and business model delivered by area, already feeding the first dashboards.
We monitor loads, ensure quality and add new sources as the business grows.